Tag

small-language-models

10 posts

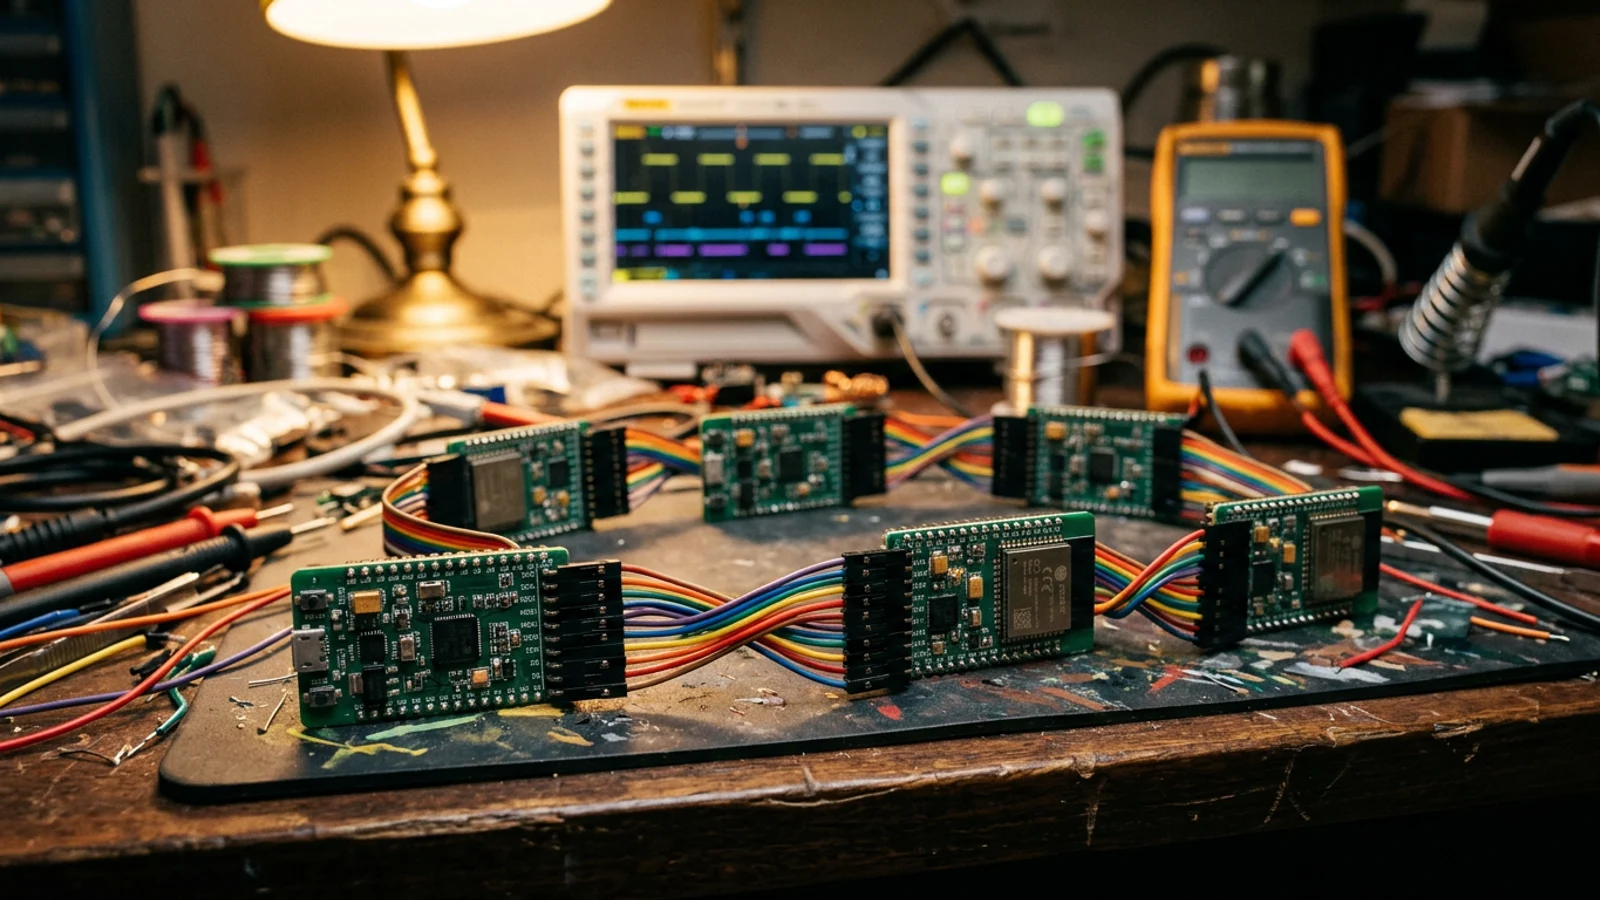
Seven $5 Chips Learn to Share an LLM, One Bit at a Time
Edge AI5 min read

Seven $5 Chips Learn to Share an LLM, One Bit at a Time

A BitNet cluster splits an LLM across seven ESP32-S3 boards, a 2-bit tool-calling model lands on GitHub, and a quantization paper gets llama.cpp 15x faster on an M4 Pro.

105 views
Read
A Classifier That Only Picks, a Model That Skips Tokens, and an AI Firm Bets 2.6B Parameters Can Do Agent Work
Edge AI4 min read

A Classifier That Only Picks, a Model That Skips Tokens, and an AI Firm Bets 2.6B Parameters Can Do Agent Work

Liquid AI ships a 2.6B agentic model for edge hardware, a 144M classifier skips text generation entirely, and a new paper shows byte-level LLMs can beat tokenized ones with sc

82 views
Read
Tiny Audio AI Models Learn to Whisper Without Ever Calling Home
Edge AI4 min read

Tiny Audio AI Models Learn to Whisper Without Ever Calling Home

Two new speech stacks and a tool-calling model push voice AI fully on-device, while Nordic and Zephyr quietly harden the hardware underneath.

85 views
Read
A 27B AI Model Shrinks to 5.9GB as Ternary Quantization Keeps Pushing the Floor Down
Edge AI5 min read

A 27B AI Model Shrinks to 5.9GB as Ternary Quantization Keeps Pushing the Floor Down

PrismML compresses a 27B model to 5.9GB, Intel's BITCOS beats the 1.585-bit ternary limit, and a 44M-parameter model claims exact arithmetic on a laptop CPU.

94 views
Read
Ternary Weights and Tiny Tanks: Small-Model Quantization Gets Concrete for Edge AI
Edge AI4 min read

Ternary Weights and Tiny Tanks: Small-Model Quantization Gets Concrete for Edge AI

A ternary 8B model, a BitNet toy for TinyStories, a fish tank run by a 14M LLM, and a Rust retrieval encoder push quantization research toward real hardware.

95 views
Read
Quantization Papers Pile Up as Researchers Argue Over Where Small AI Should Spend Its Bits
Edge AI4 min read

Quantization Papers Pile Up as Researchers Argue Over Where Small AI Should Spend Its Bits

Fresh arXiv work rethinks quantization strategy and sustainability, an Apple-adjacent paper shrinks the dictation encoder, and new silicon and Jetson guidance round out the ed

132 views
Read
A Million-Token LLM Tries to Fit On Your Phone as Tiny Voice Models Multiply
Edge AI4 min read

A Million-Token LLM Tries to Fit On Your Phone as Tiny Voice Models Multiply

An iFLYTEK spin-off open-sources a 1.7B model claiming native million-token context on-device, while a 14MB tool-caller and an open voice-agent LLM push the small-model race f

243 views
Read
A 27B LLM Shrinks to Phone Size as Edge Quantization Keeps Rewriting the Rules
Edge AI4 min read

A 27B LLM Shrinks to Phone Size as Edge Quantization Keeps Rewriting the Rules

A 1-bit Qwen derivative fits an iPhone, a healing trick beats its own teacher at 4-bit, and a dense LLM limps along on an $8 chip.

80 views
Read
Edge Dispatch: Hearing Aids Get Their Own AI Chips as On-Device Voice and Vision Push Past the Phone
Edge AI4 min read

Edge Dispatch: Hearing Aids Get Their Own AI Chips as On-Device Voice and Vision Push Past the Phone

Hearing aids ship dedicated on-device AI chips, new AI glasses land, and real-phone benchmarks show why raw specs don't tell the whole story.

119 views
Read
Edge Dispatch: Liquid AI Trains Its Way Around the Q4_0 Quality Tax, While New Papers Chip Away at What Quantization Quietly Breaks
Edge AI4 min read

Edge Dispatch: Liquid AI Trains Its Way Around the Q4_0 Quality Tax, While New Papers Chip Away at What Quantization Quietly Breaks

Liquid AI distills instead of just rounding for 4-bit LFM2.5 checkpoints, as fresh research flags what low-bit quantization costs in memory and multilingual accuracy.

123 views
Read