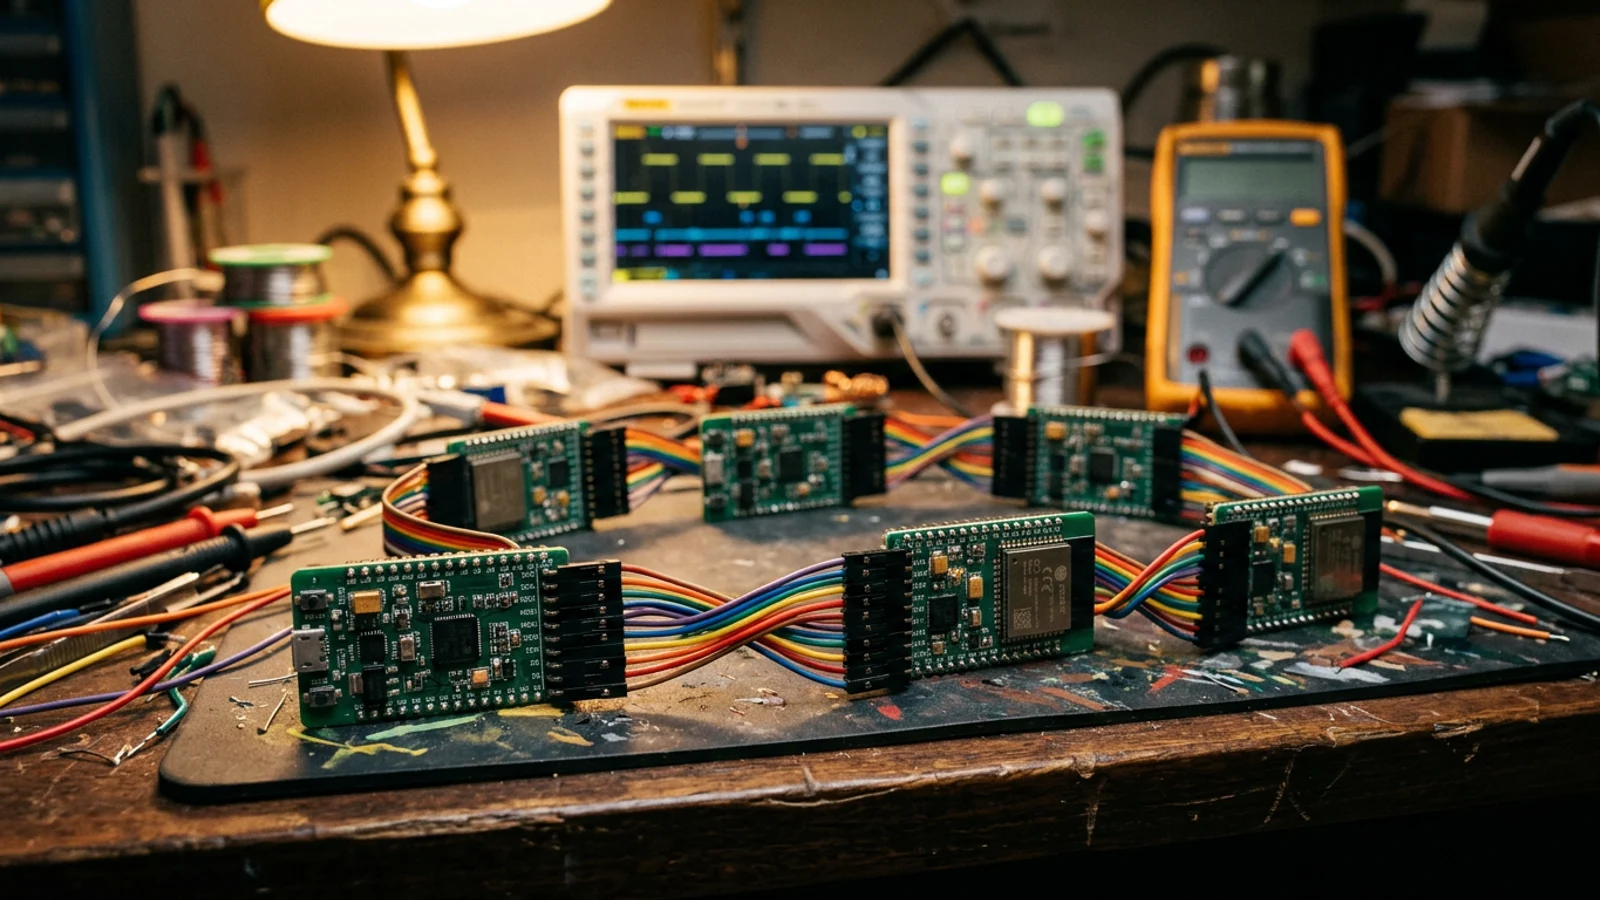
Seven $5 Chips Learn to Share an LLM, One Bit at a Time
A BitNet cluster splits an LLM across seven ESP32-S3 boards, a 2-bit tool-calling model lands on GitHub, and a quantization paper gets llama.cpp 15x faster on an M4 Pro.
Tag
9 posts

A BitNet cluster splits an LLM across seven ESP32-S3 boards, a 2-bit tool-calling model lands on GitHub, and a quantization paper gets llama.cpp 15x faster on an M4 Pro.

Liquid AI ships a 2.6B agentic model for edge hardware, a 144M classifier skips text generation entirely, and a new paper shows byte-level LLMs can beat tokenized ones with sc

AMD open-sources fused FlashAttention kernels for XDNA NPUs, Qualcomm ships a Linux preview for Snapdragon X2, and fresh research pushes tiny and trillion-scale models toward

PrismML compresses a 27B model to 5.9GB, Intel's BITCOS beats the 1.585-bit ternary limit, and a 44M-parameter model claims exact arithmetic on a laptop CPU.

A ternary 8B model, a BitNet toy for TinyStories, a fish tank run by a 14M LLM, and a Rust retrieval encoder push quantization research toward real hardware.

Fresh arXiv work rethinks quantization strategy and sustainability, an Apple-adjacent paper shrinks the dictation encoder, and new silicon and Jetson guidance round out the ed

A 1-bit Qwen derivative fits an iPhone, a healing trick beats its own teacher at 4-bit, and a dense LLM limps along on an $8 chip.

A Rockchip-powered duck robot, two offline Raspberry Pi builds, and audits exposing quantization's blind spots and mislabeled GGUF files.

Liquid AI distills instead of just rounding for 4-bit LFM2.5 checkpoints, as fresh research flags what low-bit quantization costs in memory and multilingual accuracy.