Research8 min read
Reward Hacking Is Not a Bug — It Is the Optimization Working
Reward hacking keeps surprising ML teams because they keep treating it as a bug. It's not. It's the optimizer telling you your objective was wrong.
78 views
Read Category
4 posts
Reward hacking keeps surprising ML teams because they keep treating it as a bug. It's not. It's the optimizer telling you your objective was wrong.
Speculative decoding promises faster LLM inference without touching model weights. The math holds up — but the production story is messier than the papers admit.
Mechanistic interpretability has produced real, reproducible findings. Here is an honest accounting of what those findings actually mean for engineers.
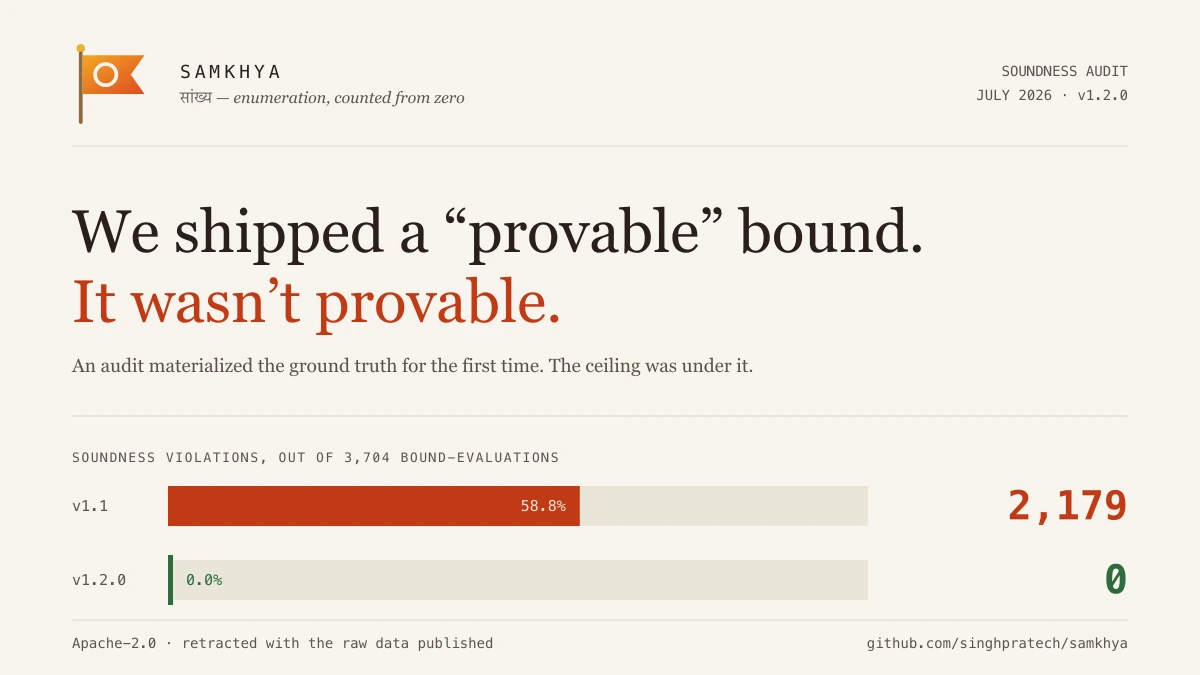
samkhya's whole reason to exist is a join-cardinality ceiling you can prove — so a model clamped under it can't wreck the query plan. In July I materialized the true output of 926 join trials and checked. The ceiling came in below the true answer in 2,179 of 3,704 evaluations. This is the bug, the repair that took it to zero, and every number I had to retract on the way.